Keep a Changelog records what changed.
Keep the Why preserves why it changed.
Same question. Same wrong turn. Same explanation, again. Your agent forgets between sessions. Nothing in the usual project structure is dedicated to remembering it.
Keep the Why is the part that remembers why. Your repository already is your project's memory — README, docs, tests, changelog, history; one layer was missing. The reasoning behind a codebase — decisions, rejected alternatives, workarounds, constraints the code alone can't explain — captured as a byproduct of working with your agent and kept as plain Markdown in context/, versioned and shared by Git. No database, no daemon, no account.
Install Read the README Linter Dashboard GitHub
Open source under the MIT license — the skill, the linter, the dashboard, and this site. No account, no telemetry, no cloud backend.
How it works
Your agent is the interface. Tell it once, then work as usual:
Install the Keep the Why skill — pick the best installation method for you from https://keepthewhy.com/installation/ — then set up Keep the Why in this project with default settings, including autostart.
The skill is the one part a project needs, and that sentence covers any of 70+ agents (Claude Code, Codex, GitHub Copilot, Cursor, Pi, Antigravity, OpenCode, OpenClaw, Hermes Agent, Cline, …). Three components are optional, one sentence each whenever you want them — the linter in CI, the dashboard on GitHub Pages or GitLab Pages, a listing in the registry: the agent knows how, offers them, and does it only when you say so. All of it, and the commands by hand: the installation page. The defaults include the start path, so from then on every session in that project loads the skill by itself. The agent records the why as it surfaces and asks only when it is genuinely unsure. You never have to tell it what to write down.
Then fill it. A new context/ starts empty and fills itself as you work. What the project already knows — in commit messages, pull requests, issues, old docs and people's heads — is one sentence away: "Go through the git history, pull requests, issues and existing docs, and collect the reasoning that is already there into context/." What the agent cannot back up it marks unknown, never made up. For what lives only in someone's head: "Interview me about this project." More on the installation page.
Keep it current. After a skill update, in a new session: "Migrate this project to the installed Keep the Why version." The agent compares the project's context-schema with the skill's version, applies the migrations in between and raises it — and offers the same by itself when it notices the project is behind.
Capture
The agent notices rationale as it surfaces — a decision, an alternative that lost, a workaround, a change that was started and abandoned — and writes it down, without being asked. No separate documentation step. An existing repository can start late too. History, issues and code give back only part of the past why — but from that point on the reasons that matter are written down once, never again, and the gaps close over time. Autonomous agents with no human in the loop too: in a session declared unattended, the agent writes what it found and flags it pending-confirmation — recorded now, confirmed by the next person who looks.
Install → · Autostart → · Continuous capture → · Retrospective →
Check
keep-the-why-lint validates the structure — locally, in CI, or both — required fields, valid values, index consistency, plus security checks such as hidden Unicode and others. It says plainly what it cannot check: whether a recorded reason is true. That part stays with review, in the same pull request as the code. Optional, not required: the skill works without it, and you add the linter where you want the extra check.
Keep & Share
Everything lives in context/, one file per topic, versioned with the code. A lean index tells an agent what to load. No daemon, no database, no service — anything that can read a repository can read it. Once merged, the why sits in the history under the same review, permissions and CI as the code. That layer — Git, on GitHub, GitLab or any other host — is what turns a local file into shared knowledge.
Use
The next session — yours, a colleague's, an agent's — loads the index first and reads the why before touching the code. An agent that finds the reason explains it and builds on it instead of repeating the attempt; one that finds nothing says so and asks, instead of guessing. That is what the capture was for.
Install → · Autostart → · Agent matrix → · Trust model → · Audit the data →
What it leaves behind
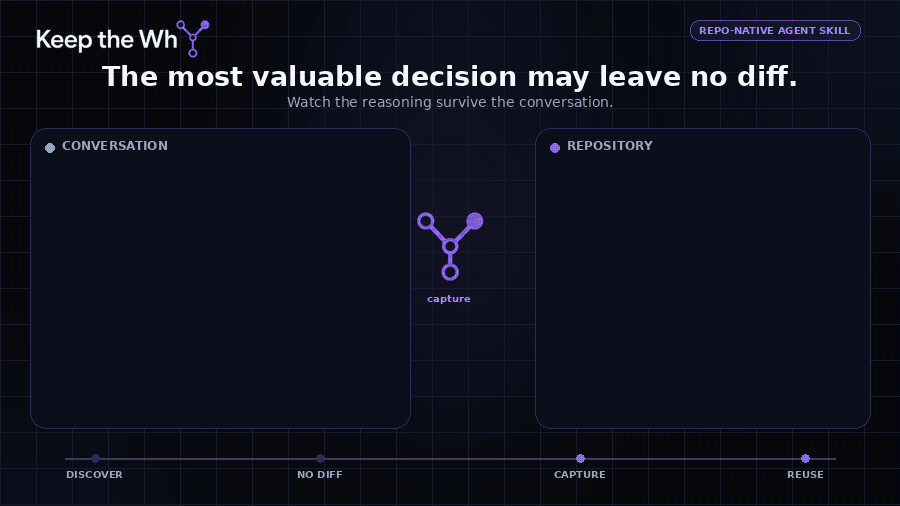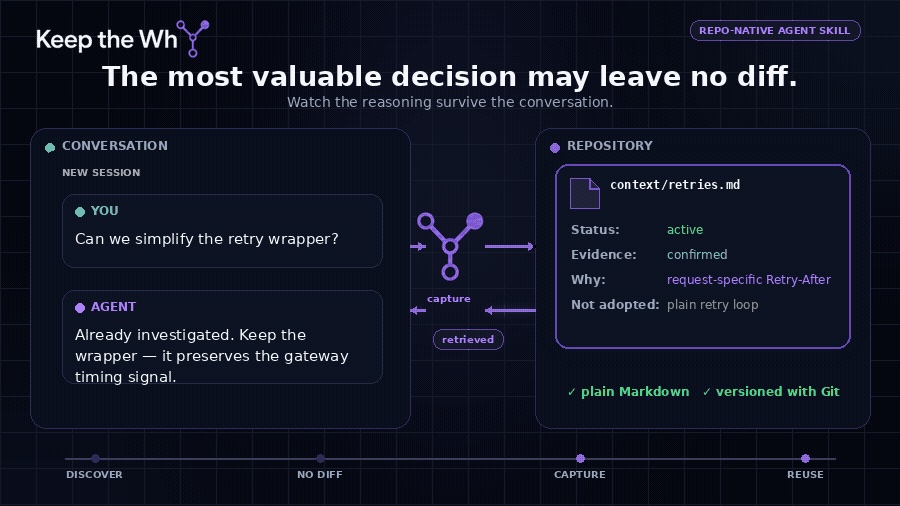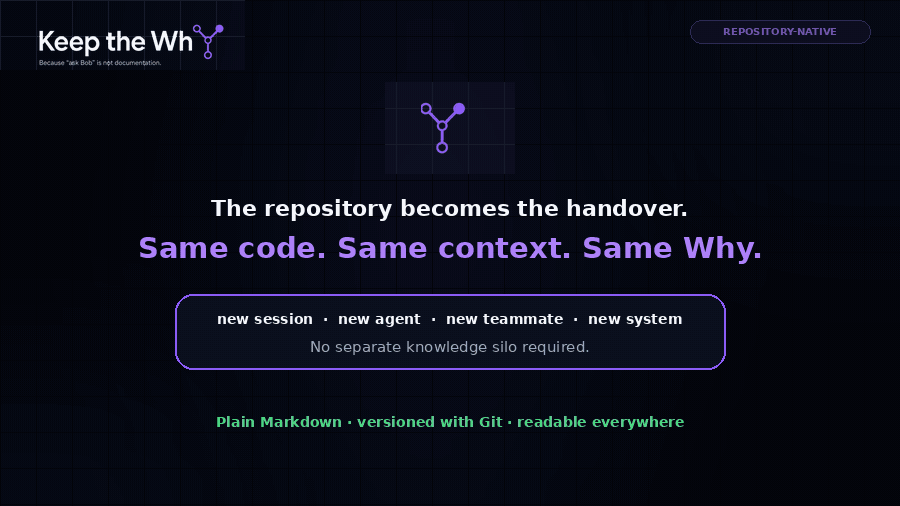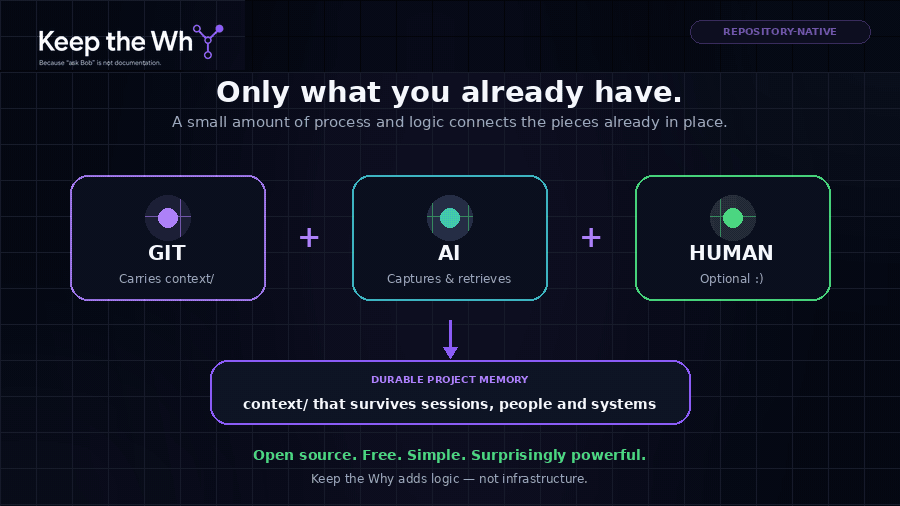
context/retries.md
Why retry_with_jitter isn't a plain retry loop
Id: 7ba48019-a710-4fa4-b6ff-b741d69ca50b
Type: constraint
Status: active
Evidence: confirmed
Source: discovered while considering simplifying it, 2026-07-22
The payment gateway's rate limiter returns 429 with a per-request Retry-After header. A fixed-delay retry loop would frequently retry before the limiter resets, causing repeated 429s under load.
Considered: replacing it with a plain retry loop, since the wrapper looked like unnecessary complexity with nothing documenting why. Not adopted once the Retry-After behavior surfaced during review.
Decisions that shipped, alternatives that lost, workarounds, constraints — Keep the Why keeps the reasoning behind all of them: one entry per topic, plain Markdown, reviewed in the same pull request as the code, and found through a one-line-per-topic index, so an agent loads only the topic a task touches. This one is the case where it matters most: a change that was started and then dropped, so there is no commit, no diff, no pull request — and without the entry, no trace. Every entry says how well its claim is backed (Evidence) and whether it still holds (Status); "unknown" is a valid answer. The full example → · Field reference →
Git does the rest
context/ is files in the repository, so everything Git and your host already do for code, they do for the why — nothing to set up, nothing to run, no second system to keep in sync.
Permissions
Who may write the why is who may write the code: branch protection, required reviews, CODEOWNERS on context/ if you want a named owner — the same rules, no second access list. The skill never commits on its own; an entry reaches the history the way code does, through a commit a person made.
Distribution
git clone ships it. Every checkout, every CI runner, every agent on every machine has the whole why, offline, at the commit it is working on. No sync, no account, nothing to install to read it.
Review
A reason enters the record in the same pull request as the change it explains; the reviewer reads the diff and the why side by side. The linter checks the shape, review checks the truth — the one part no tool can.
Forks
A fork carries the why with it and keeps writing its own. Citations still point at the published repository, not the fork — canonical is taken from upstream in a fork checkout — so a contributor's branch brings the reasoning back with the code, and a fork that diverges on purpose records why.
Branches
Two branches that add entries merge like code. The index has a fixed 0–9, A–Z heading skeleton for exactly that: parallel additions land under different headings instead of in the same line, and a merge conflict in context/ is the ordinary kind, resolved the ordinary way.
Blame & history
git blame on an entry says who recorded it and when; git log says when its Status changed; git log -S <Id> finds every place an entry is cited. Every entry has an audit trail, and nobody had to build one. The dashboard's Authors and Timeline views read exactly that.
Live Dashboard

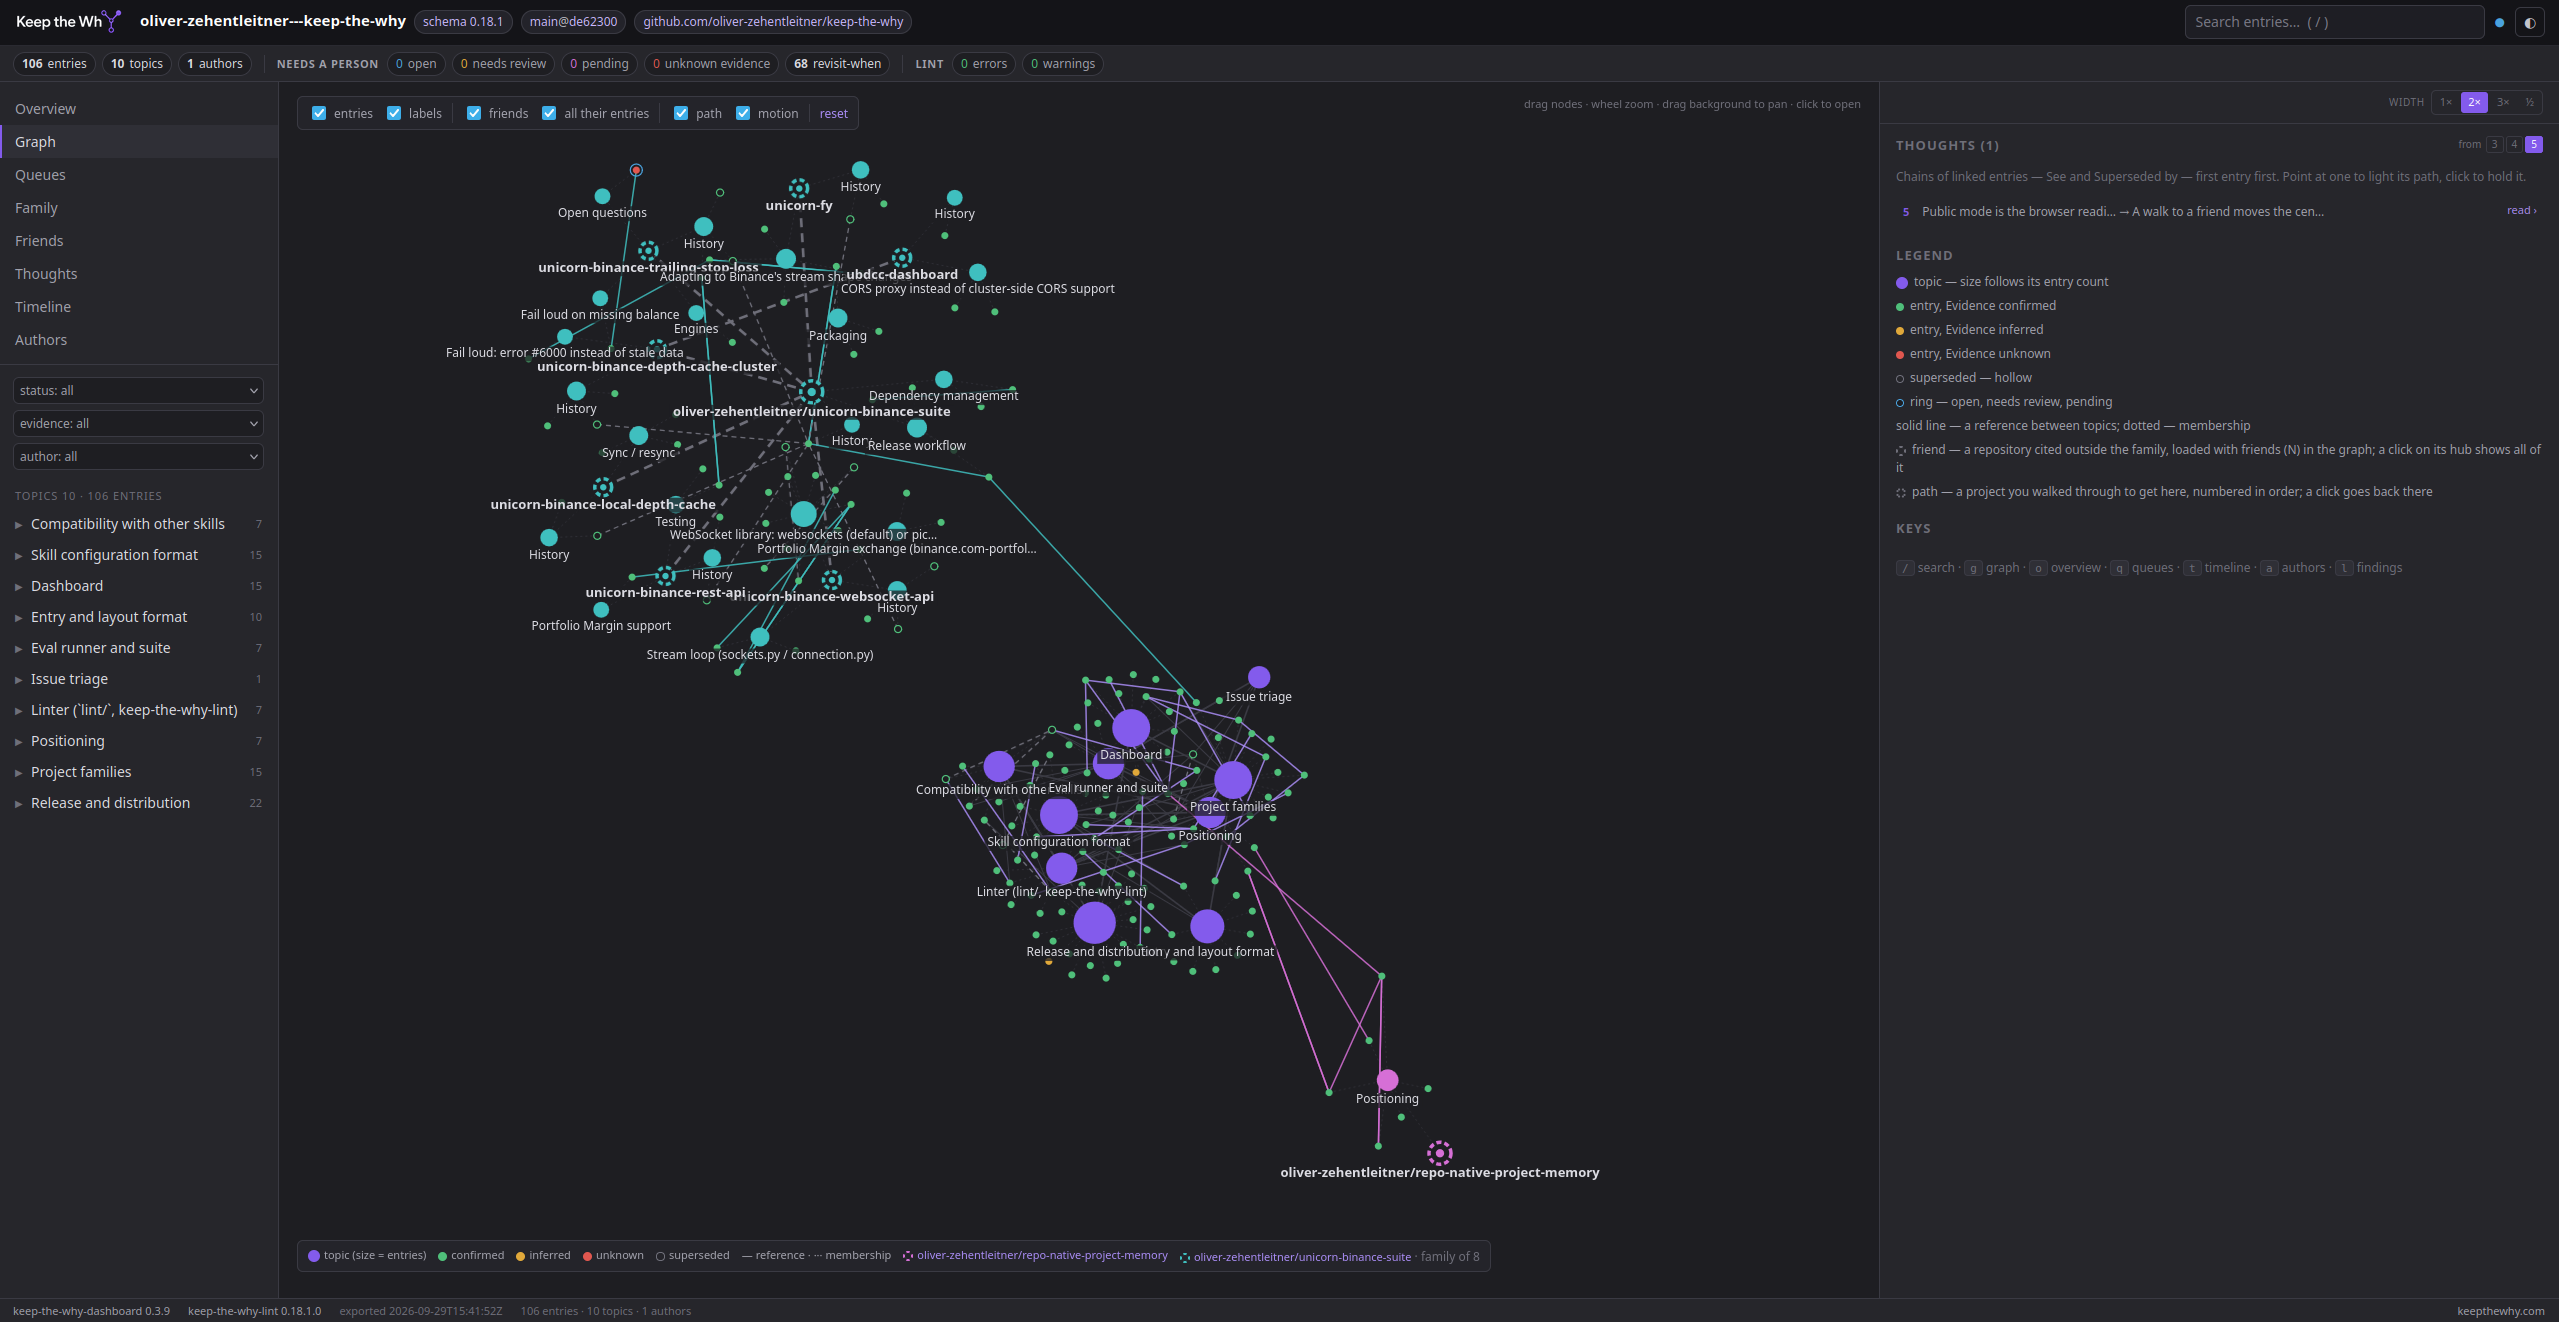
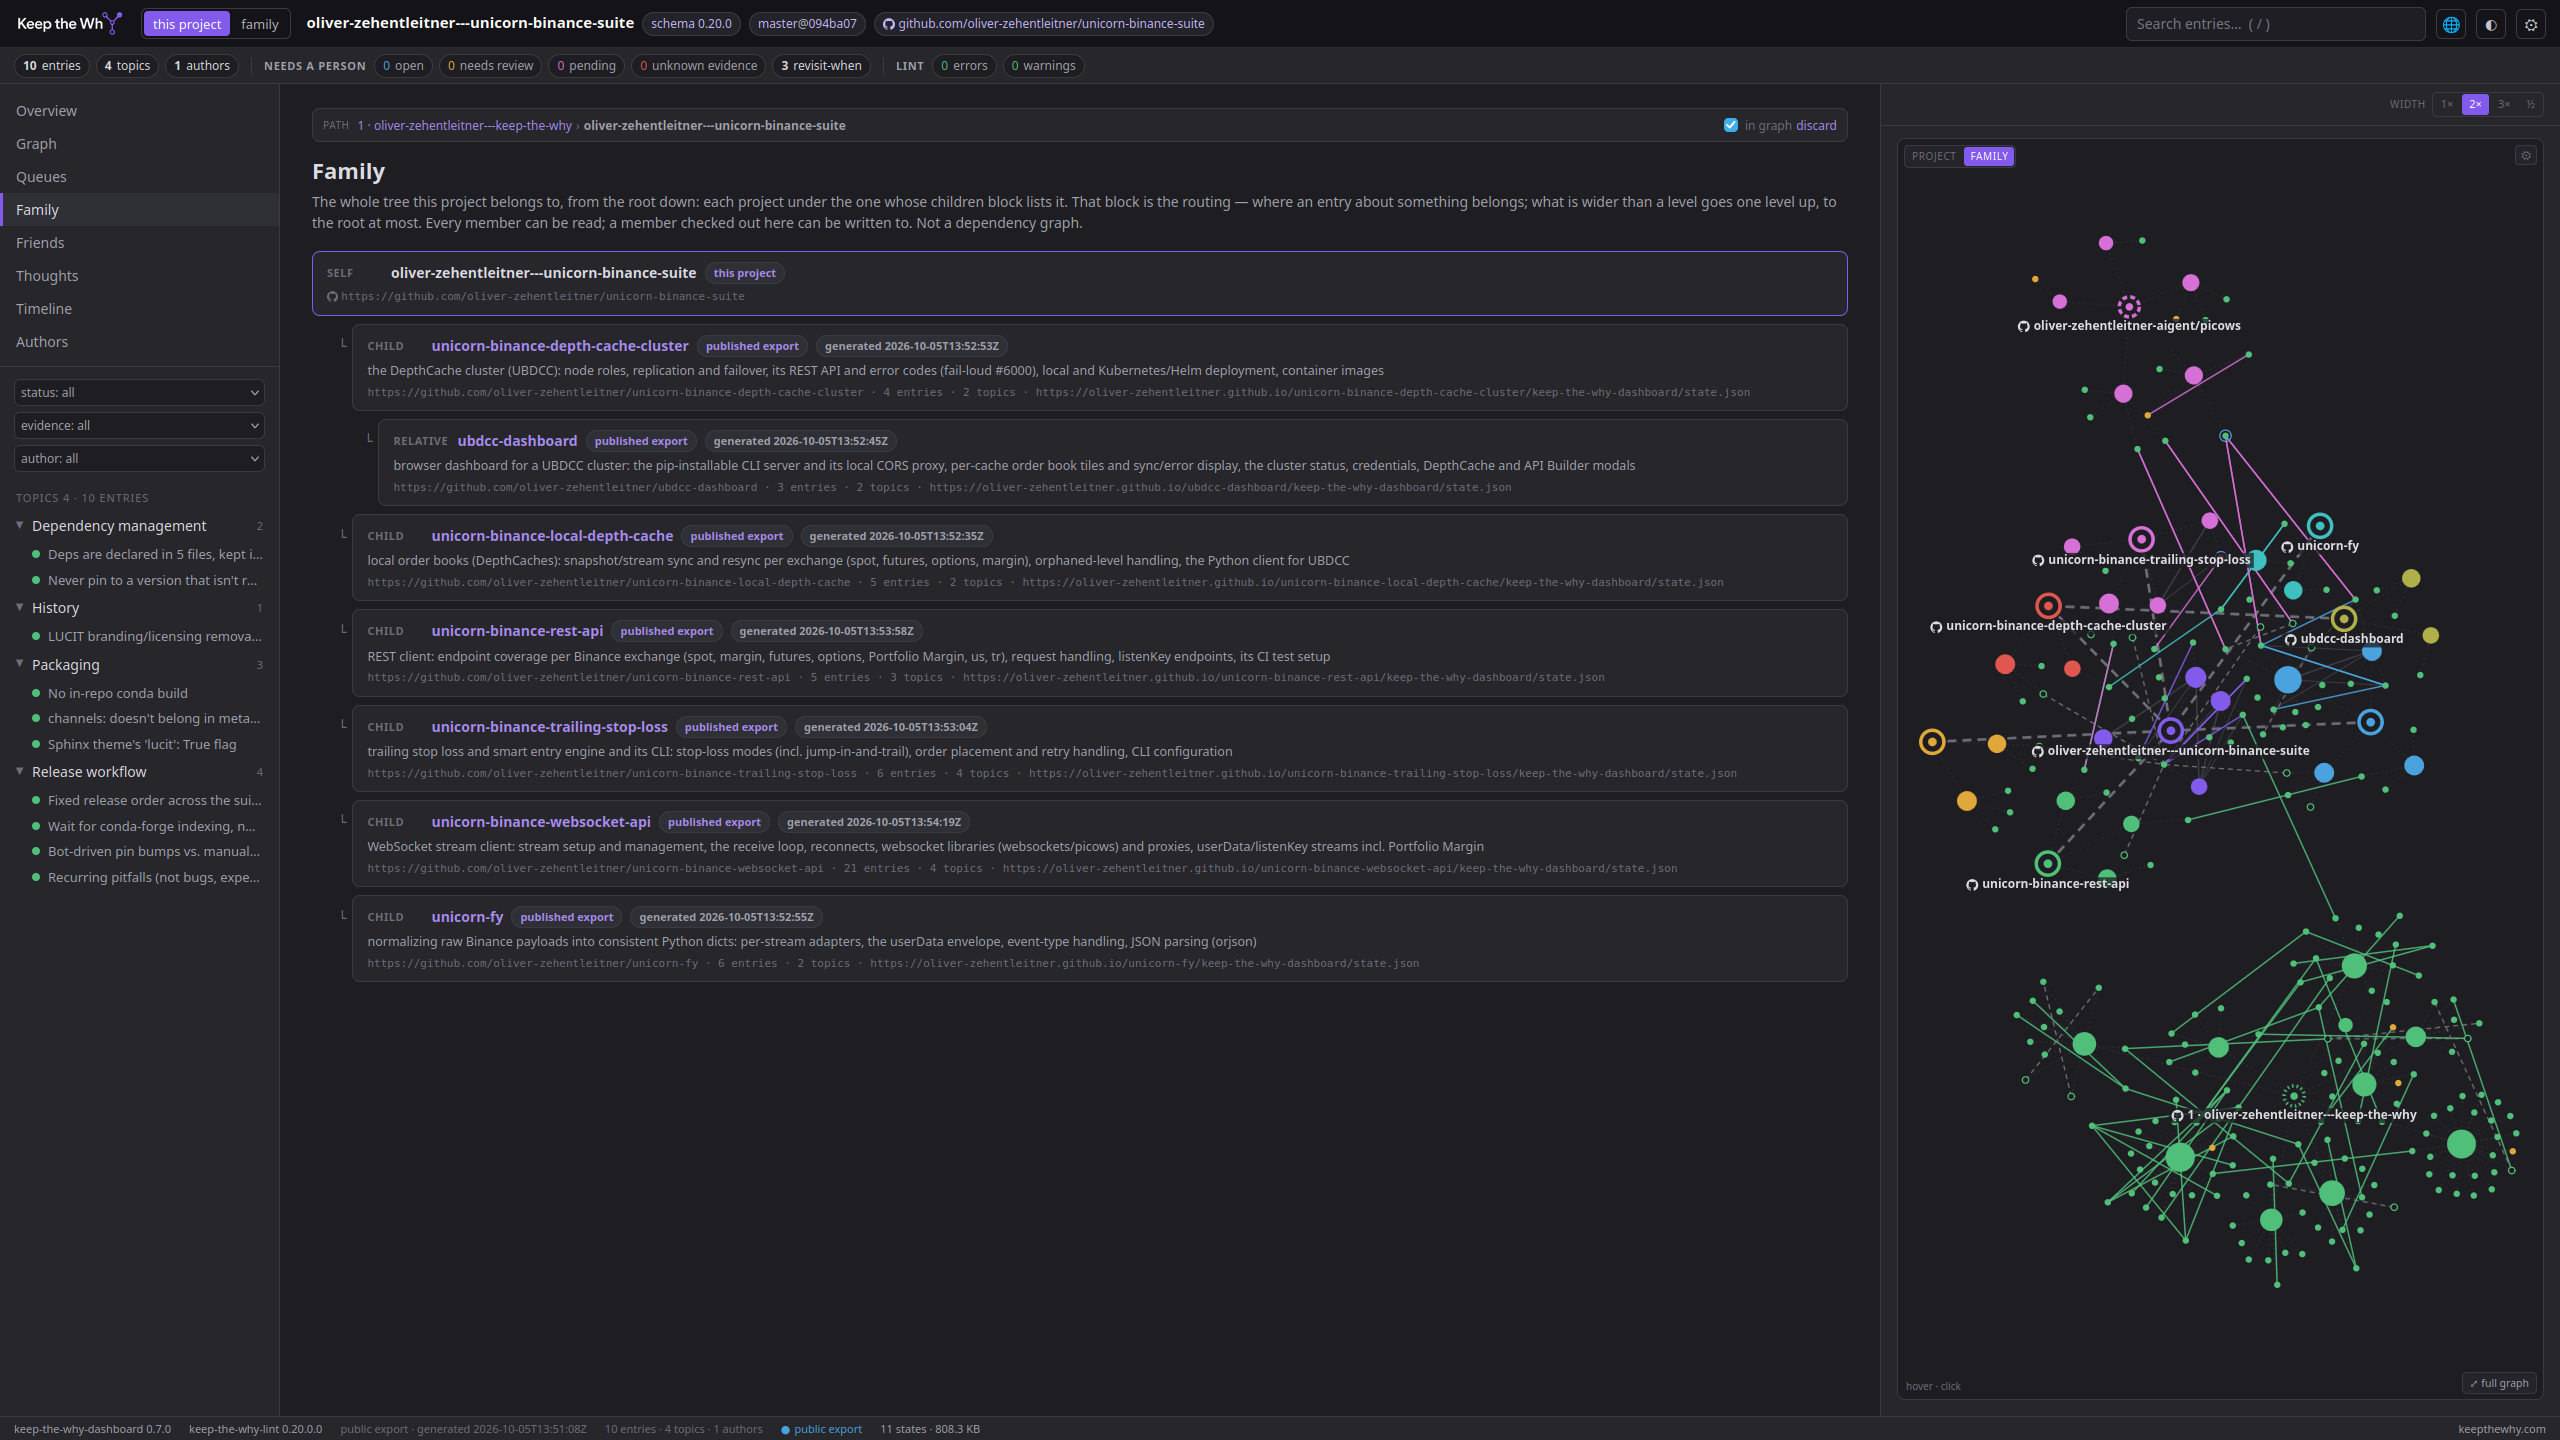
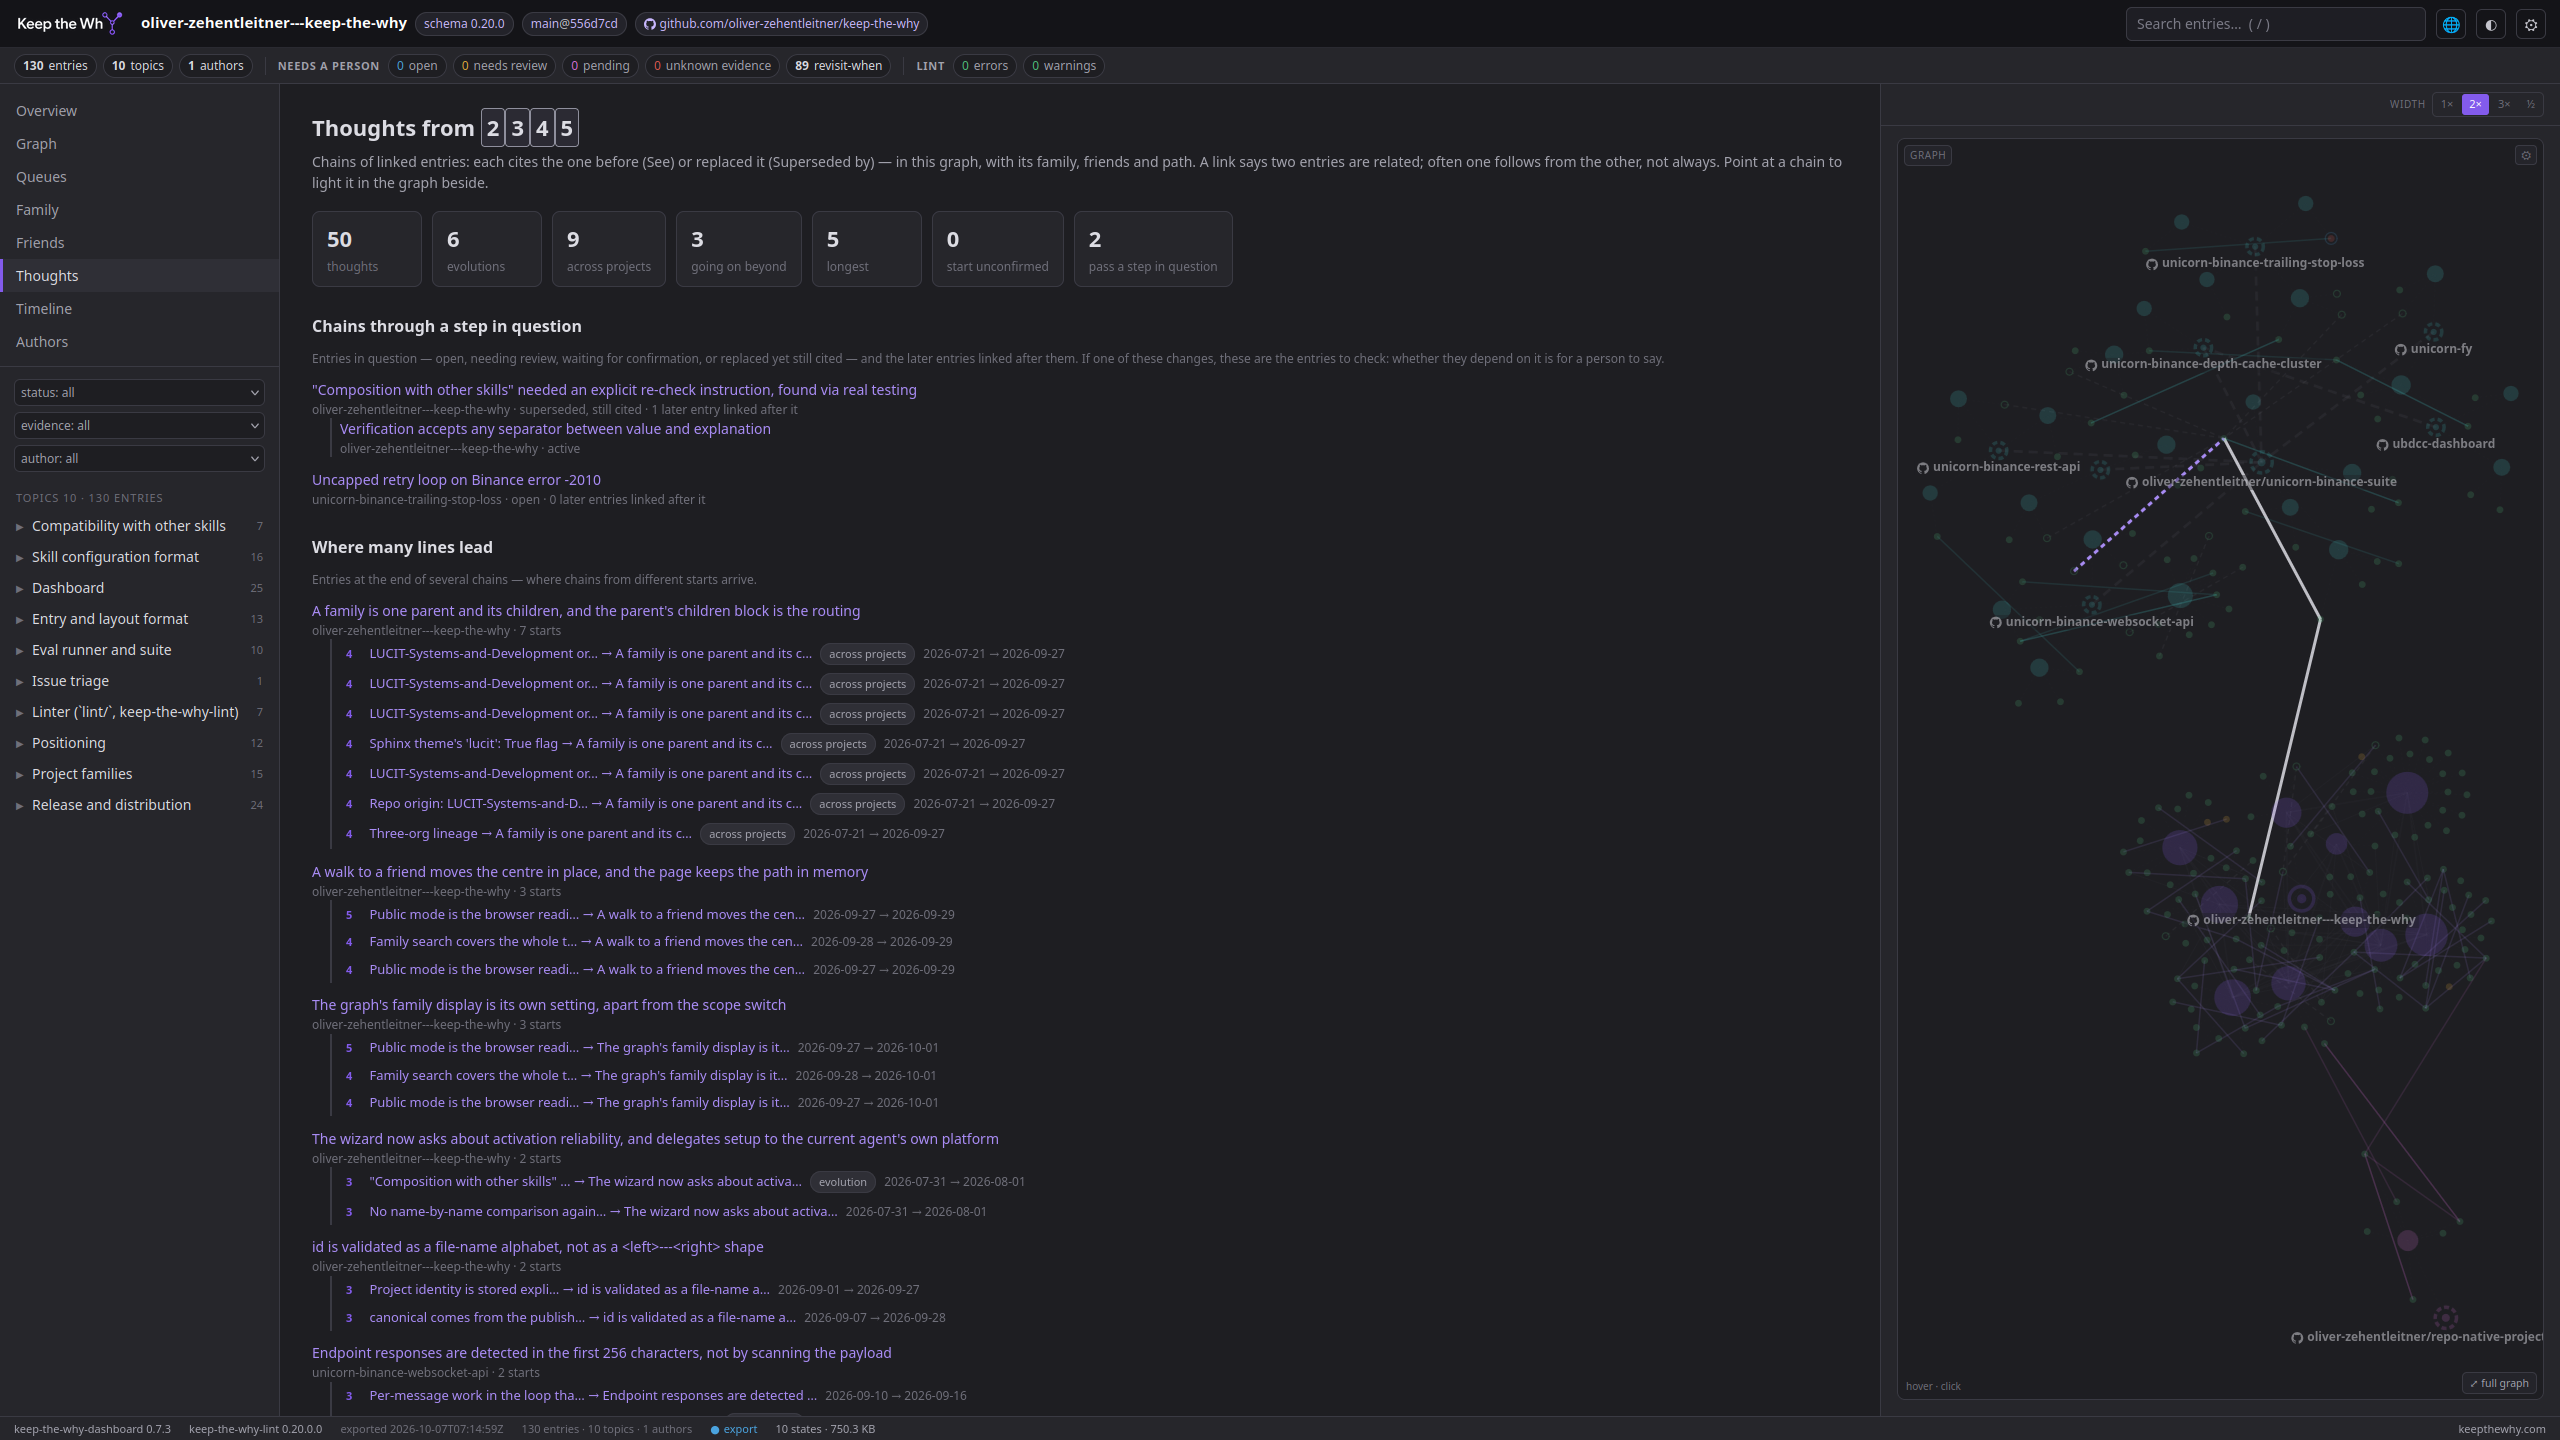
The dashboard — a read-only view over context/ and its Git history: who recorded what, when a status changed, what still needs a person. It follows the reasoning beyond one repository: the project's family, its friends — the repositories its entries cite — and the thoughts running through them, lines of decisions each citing the one before. Run locally, it updates as the project changes. Static exports, each rebuilt with its project's docs deploy: Keep the Why's own context/ — a mono repository, the export behind the screenshot — repo-native project memory, a single repository, and the UNICORN Binance Suite, a family of eight repositories. Dashboard → · Mono repository example: Keep the Why → · Single repository example: repo-native project memory → · Multi repository example: unicorn-binance-suite → · 🌐 The globe: every listed project, and how they cite each other →
One repository or many
A .keep-the-why marks a project, and the project is the nearest one above wherever the agent works — the way Git finds .git. However your code is laid out, the why sits next to it.
Single repository
One .keep-the-why, one context/. The common case — nothing to configure.
Mono repository
One context/ for the whole tree, or one per sub-project — each with its own settings, and still one family under the repository's root.
Example: Keep the Why — skill, linter and dashboard, one context/ → · both mono layouts →
Multi repository
A family: one parent project lists its children, one line each on what belongs where. The why lives once, in the project it binds, and is cited from everywhere else — families can nest, a suite, its cluster, the cluster's dashboard.
Example: the UNICORN Binance Suite's dashboard → · its family, eight repositories →
Nested repositories
A repository inside another — a submodule, a vendored checkout — is a project of its own. The nearest .keep-the-why wins; nothing leaks across.
Linked across all of them. Any project can cite an entry in any other — in its family or not, one repository or eight — with a See line naming the other repository and the entry's Id; a reworded heading or a split file doesn't break it. The dashboard follows those links: family members show as one, the other repositories cited as friends, and the reasoning that runs through them as thoughts — chains of entries in which each one cites the one before — how the recorded decisions connect, across repositories. See it: Keep the Why with its friends → · the thoughts across them →
Layouts → · Families → · Dashboard: family, friends, thoughts →
Tested, measured, stated plainly
Tested with: Claude Code, opencode, Pi, Hermes, and more — see the full eval suite and the agent × model matrix for what's actually been run against what, and how.


The skill is validated against the Agent Skills spec on every push; this repository's own context/ is linted by its own linter, in strict mode; the package is scanned by two independent registries — one of them, the HOL AI Plugin Scanner, on every push in this repository's own CI — currently 94/100 with no high finding; the workflow fails below 80 or on any high finding.
And one controlled experiment on the core claim: twenty fresh agent sessions, the same codebase, the same request to simplify a retry wrapper. Without a recorded reason, seven of ten offered the already-rejected simplification again. With one context/ entry, all ten found it and none did. The experiment → · transcripts and grades
What this is not
Not session memory — and it does the job session memory is wanted for. Session memory remembers what happened; project state remembers where the project is; the why layer preserves why it became what it is. This is the third — not a transcript or activity log. But what people reach for session memory to fix — the agent forgetting between sessions — this fixes at the source: the reasoning is in the repository, so every session starts with it, on every machine and in every tool, for the whole team. Read the two side by side.
Not magic. No tool prevents knowledge from decaying on its own. This lowers the friction of the discipline that keeps documentation honest; it doesn't replace it.
Not a platform. No daemon, no database, no account. Just Markdown, Git, and the why your project would otherwise lose — and a read-only dashboard over both, for when you want to look.
The full list, and where Keep the Why fits next to ADRs, AGENTS.md and Keep a Changelog: README →